LLM-as-a-Judge & reliable automated evaluation
How LLMs are used to judge software artifacts — and what it would take for their verdicts to be trustworthy.
LLM-as-a-Judge for SE 2026Software engineering AI systems
Ph.D. Candidate Singapore Management University
I am a Ph.D. candidate in the SOAR group at Singapore Management University, advised by Prof. David Lo. Previously, I received my M.Sc. in Software Engineering and B.Sc. in Computer Science from University College London.
I develop methods to evaluate and test LLMs and AI agents, with a focus on their reliability in software engineering.
Understanding when we can trust LLMs to judge software artifacts.
LLM-as-a-JudgeMeasuring code-generation capabilities with realistic, complex tasks.
BigCodeBenchFinding failures in learning agents through systematic testing.
Deep RL testingHow LLMs are used to judge software artifacts — and what it would take for their verdicts to be trustworthy.
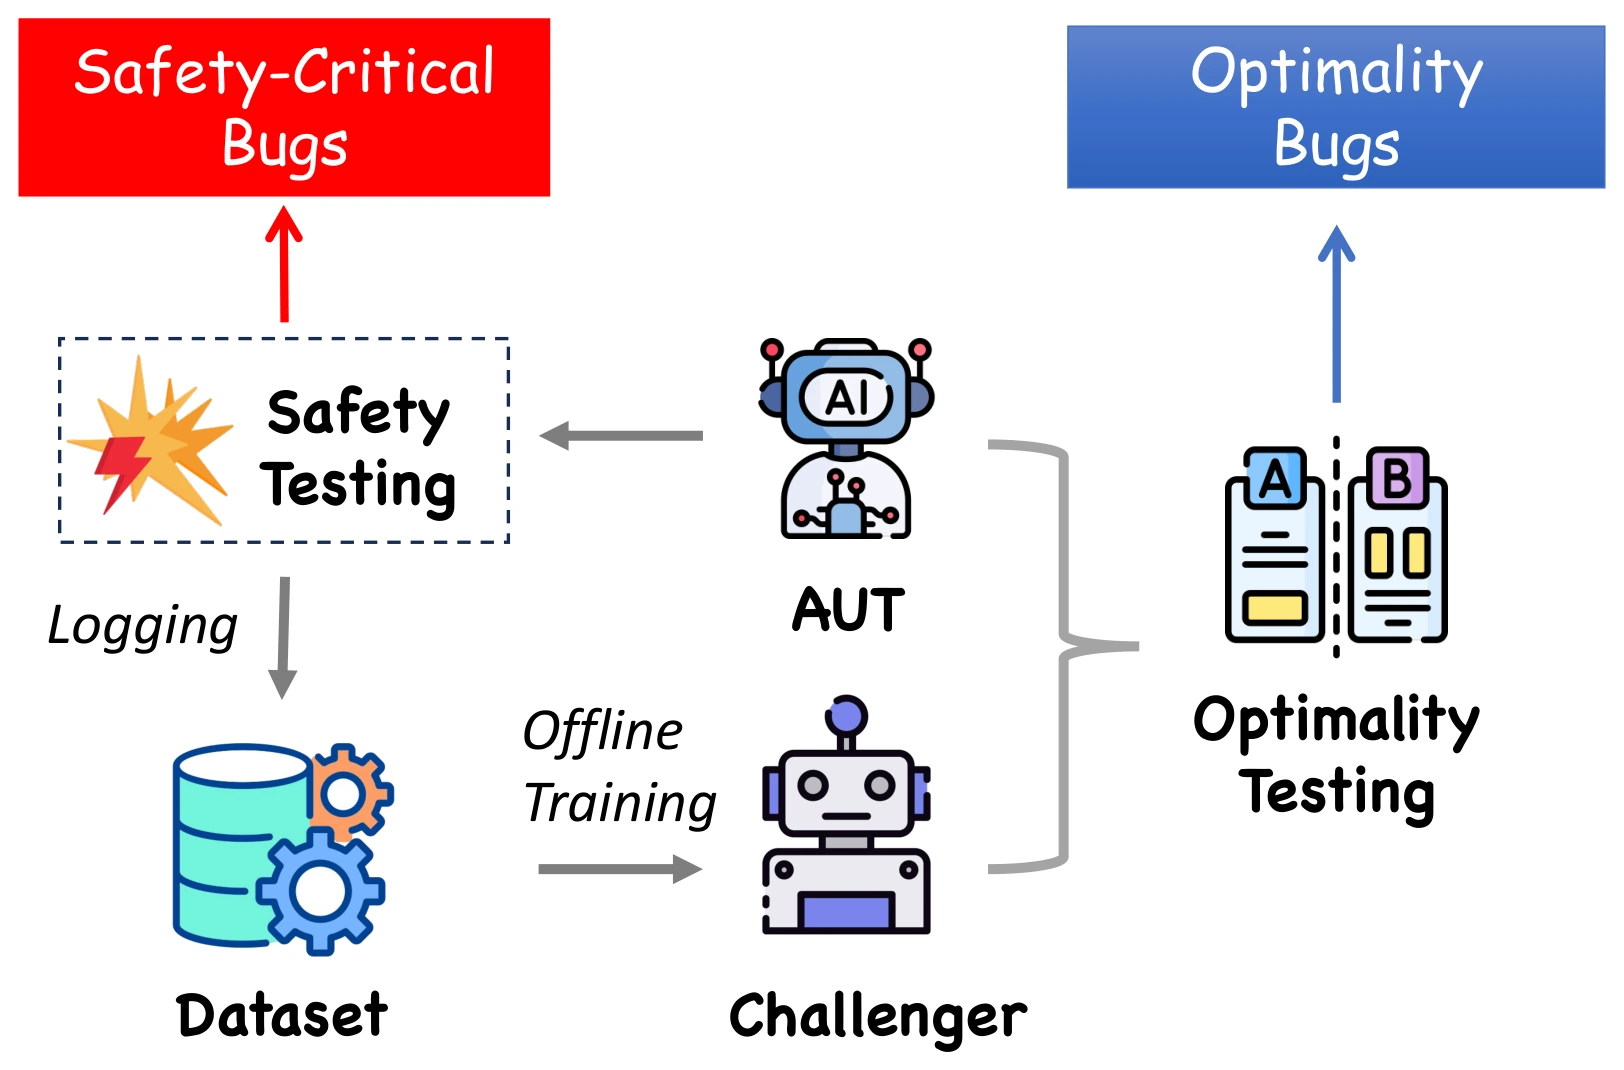
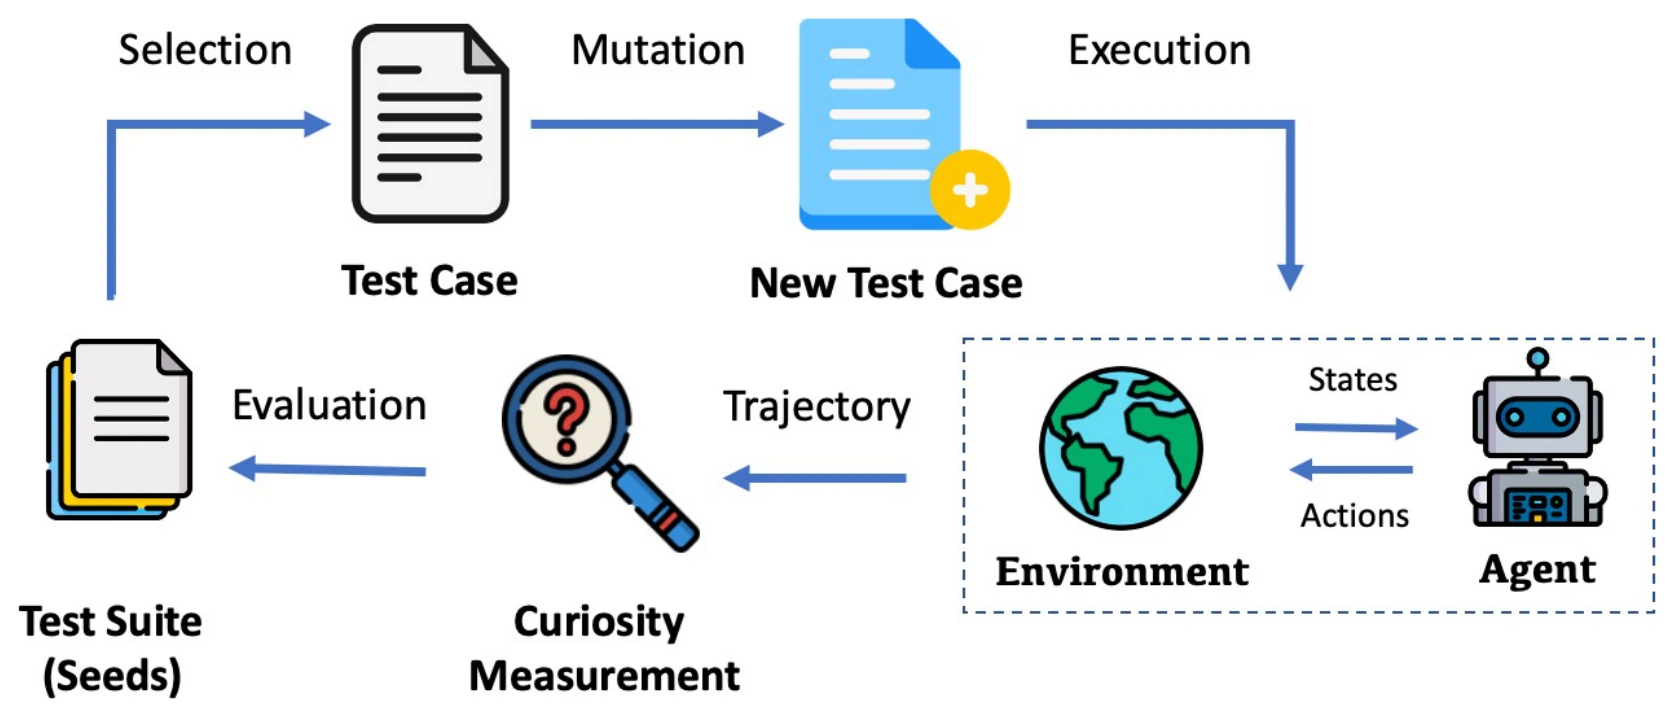
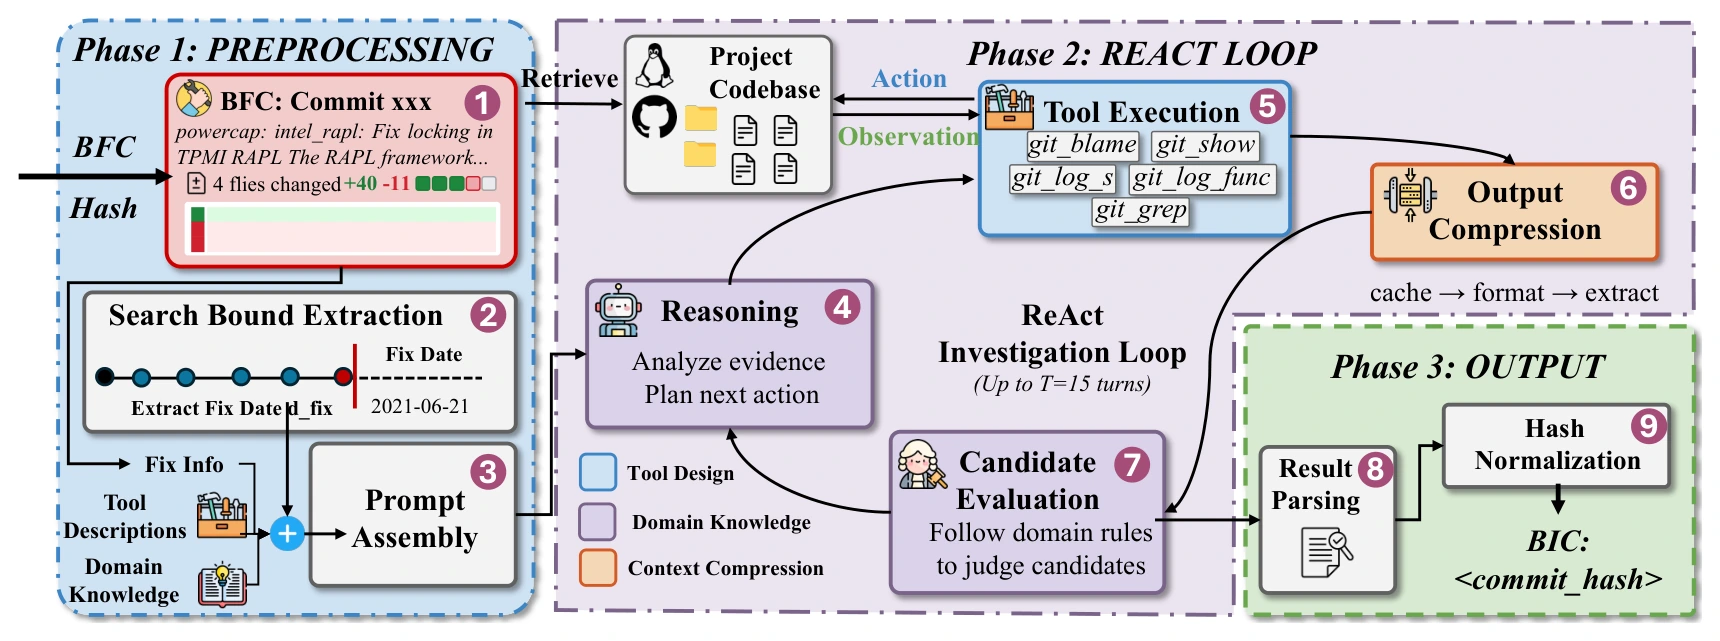
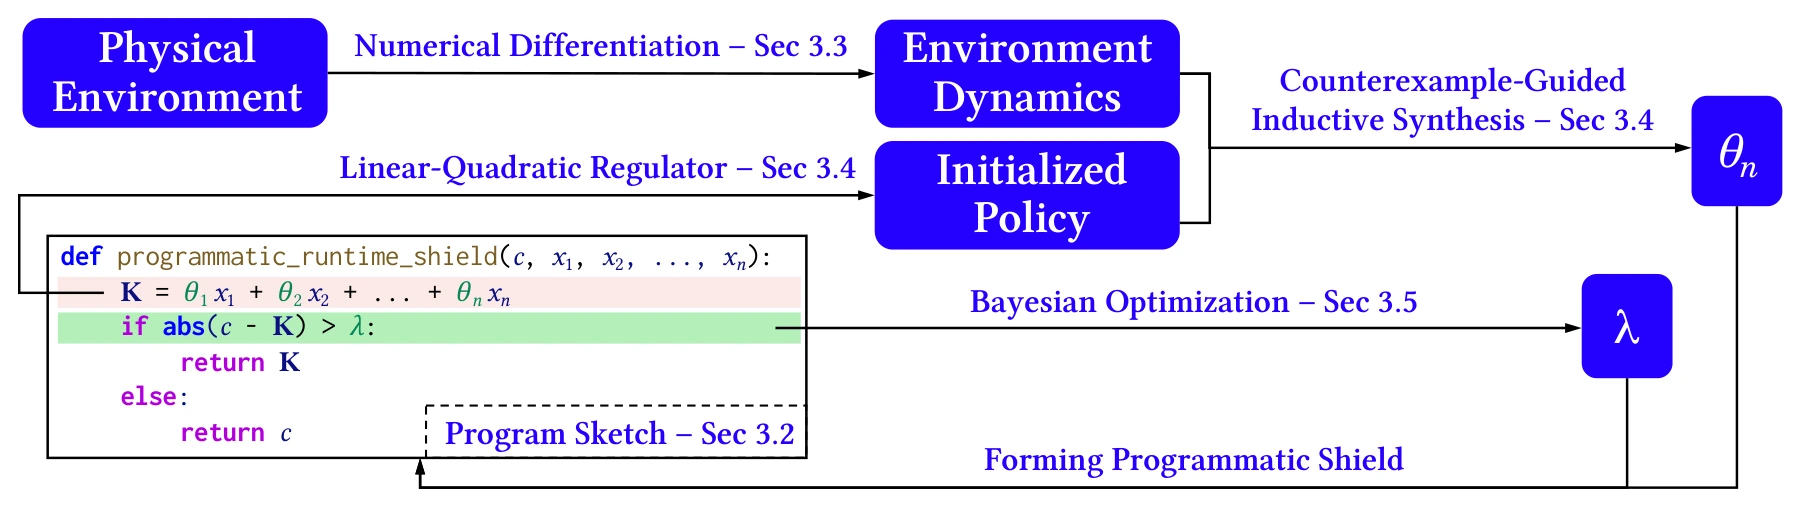
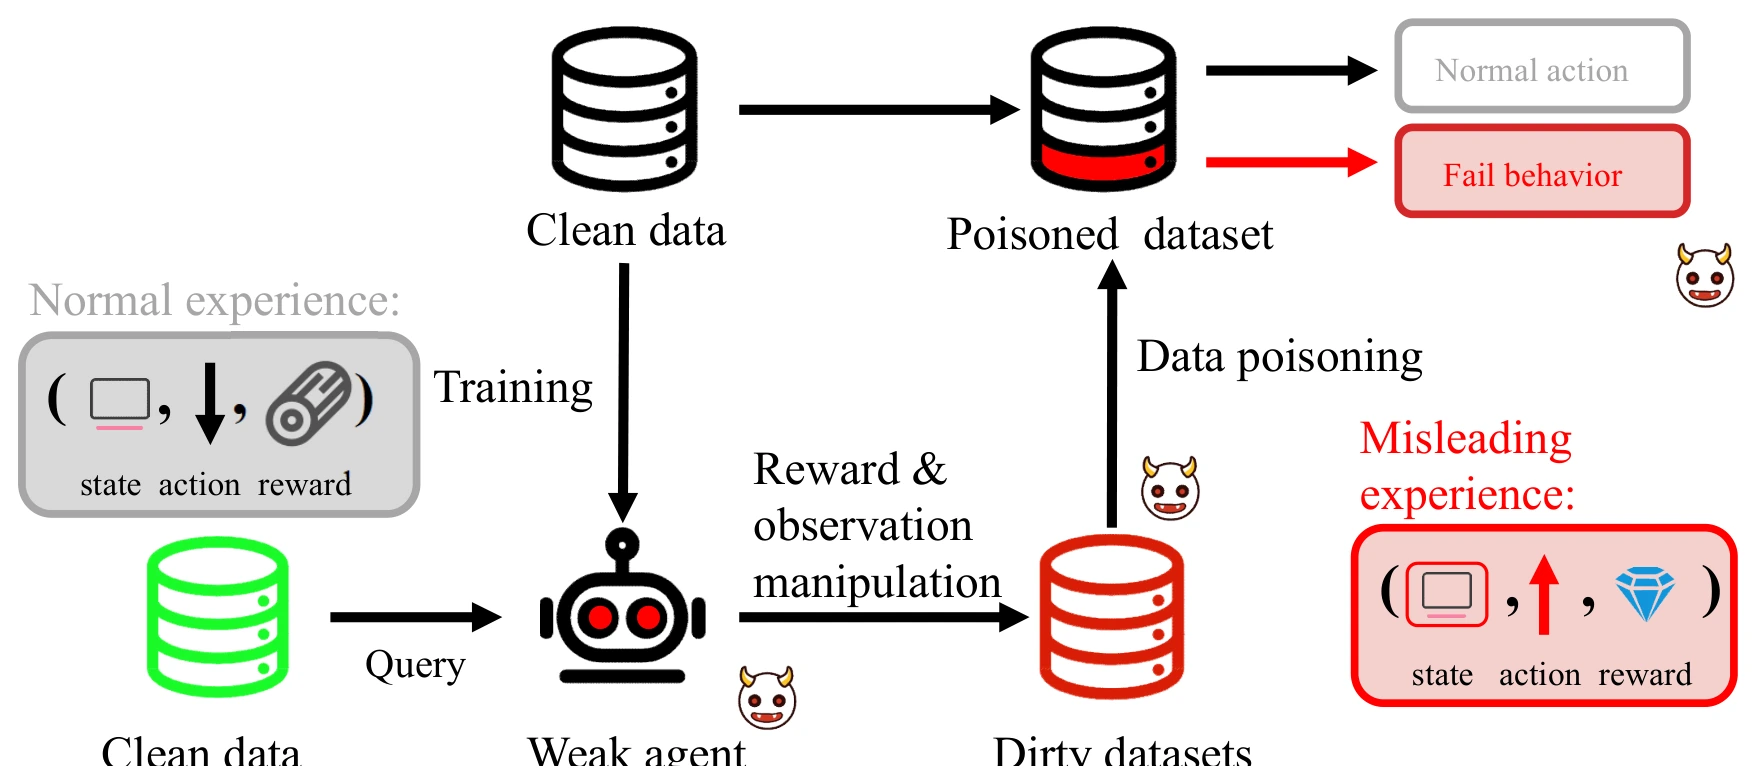
LLM-as-a-Judge for SE 2026Curiosity-driven and self-referential differential testing for deep-RL and sequential decision-making systems; runtime safety shields, safety-violation search, and backdoors in offline RL data.
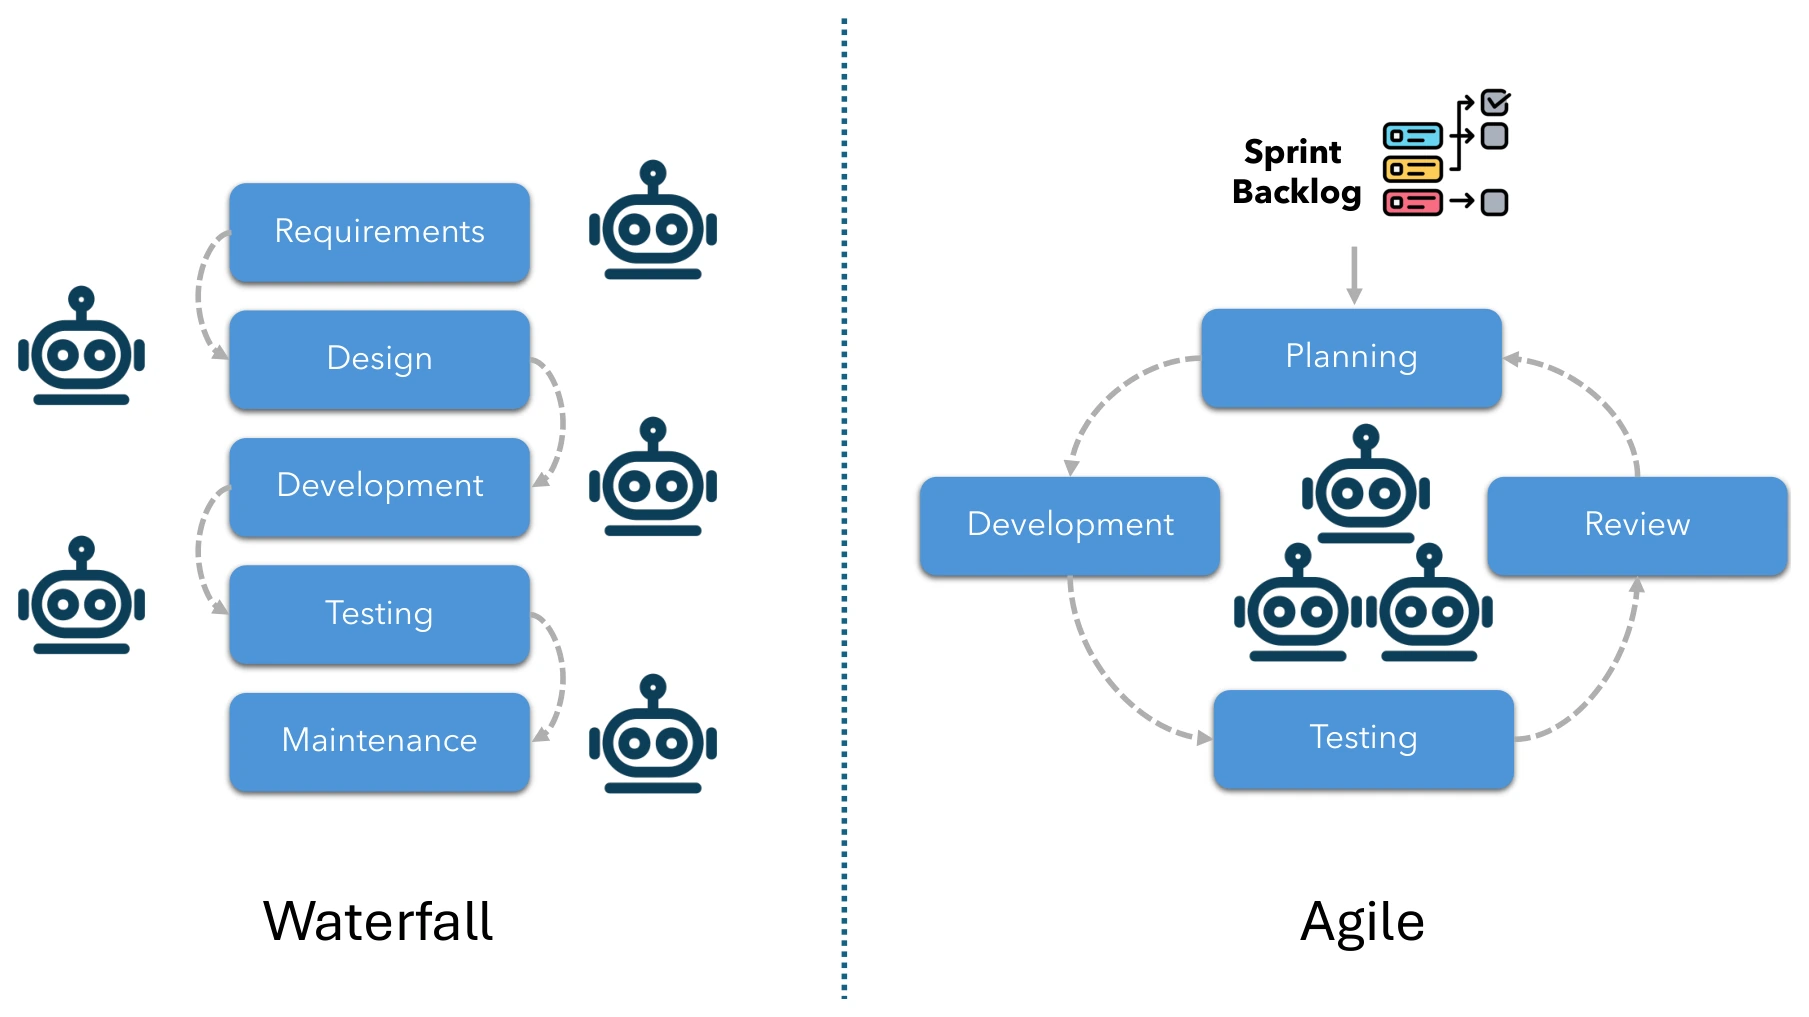
CureFuzz 2024 Self-referential differential testing 2026 Runtime shields 2026 Safety violations via proxy programs 2025 Baffle 2024A literature review and vision for LLM-based multi-agent systems in SE, and chaos engineering for agent systems.
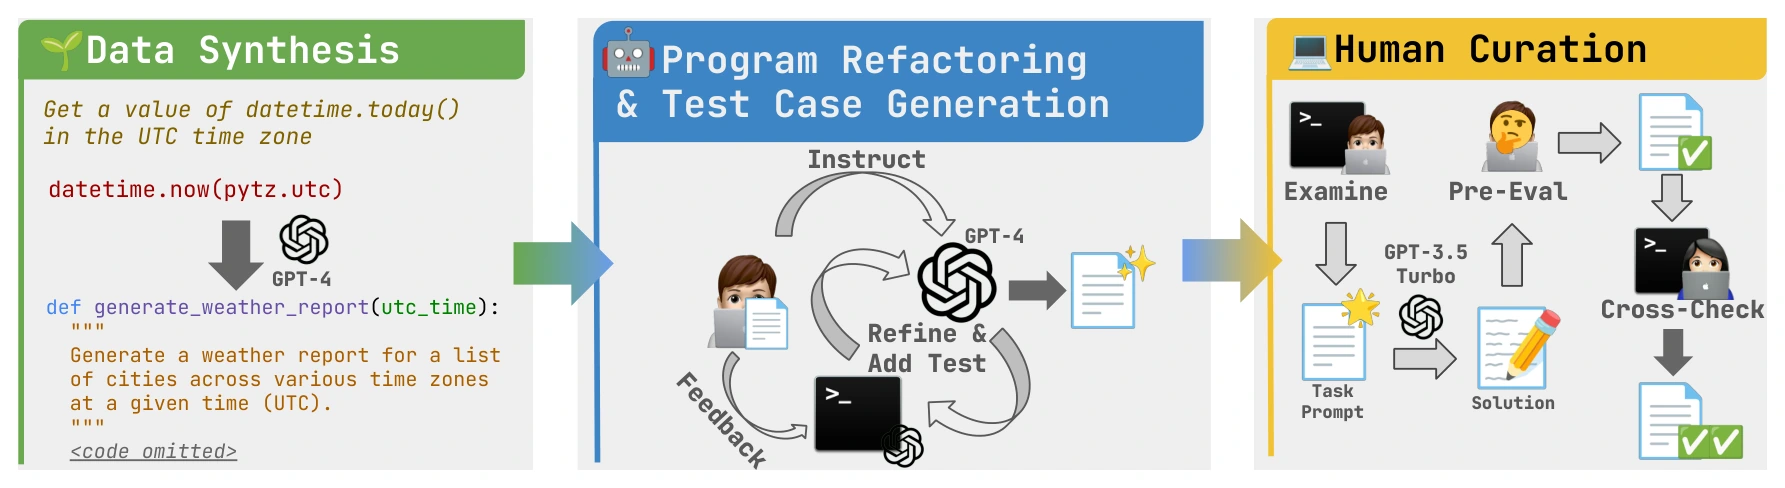
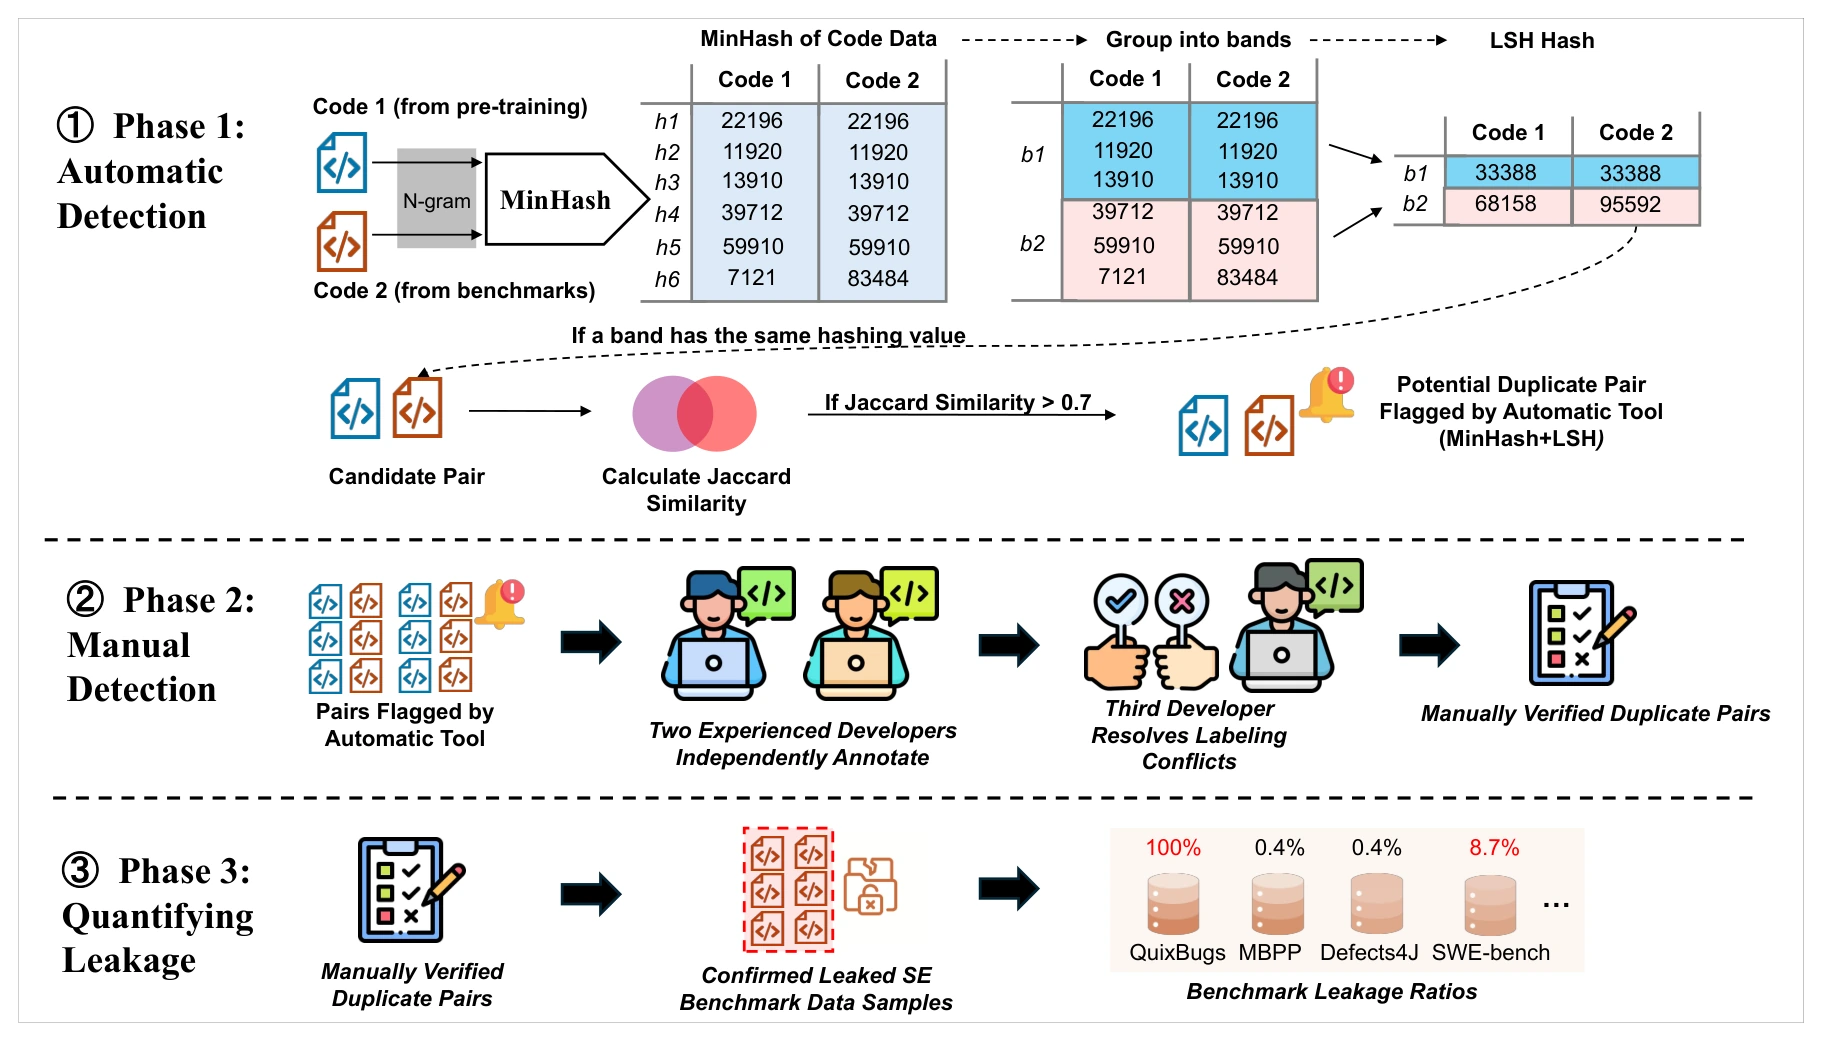
LLM multi-agent systems for SE 2025 AgentChaos 2026BigCodeBench, whose public leaderboard covers 160+ models; a critical assessment of SE benchmarks; reference-free evaluation; and data leakage across 83 SE benchmarks.
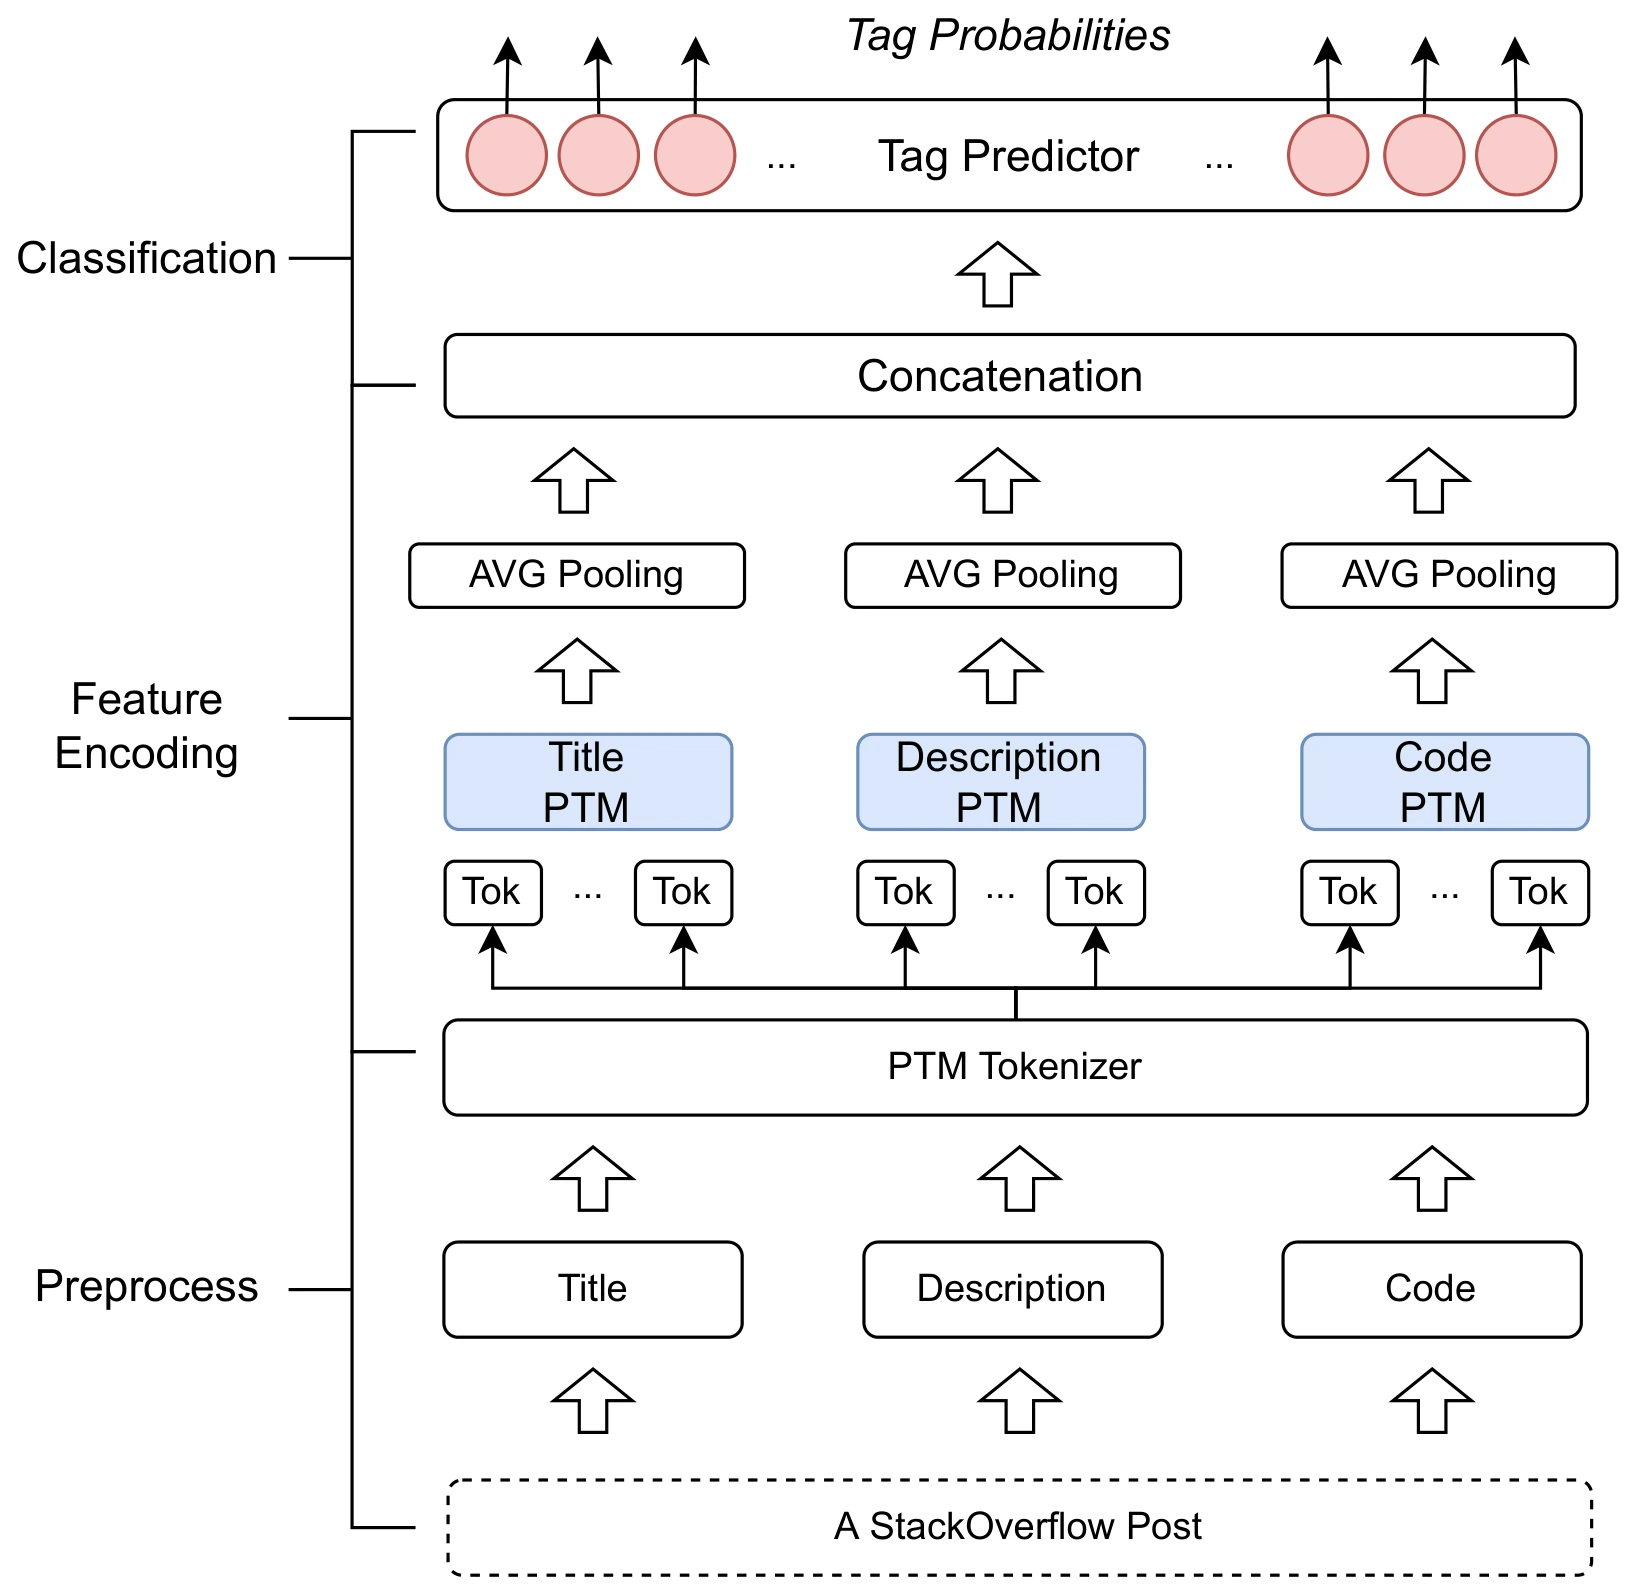
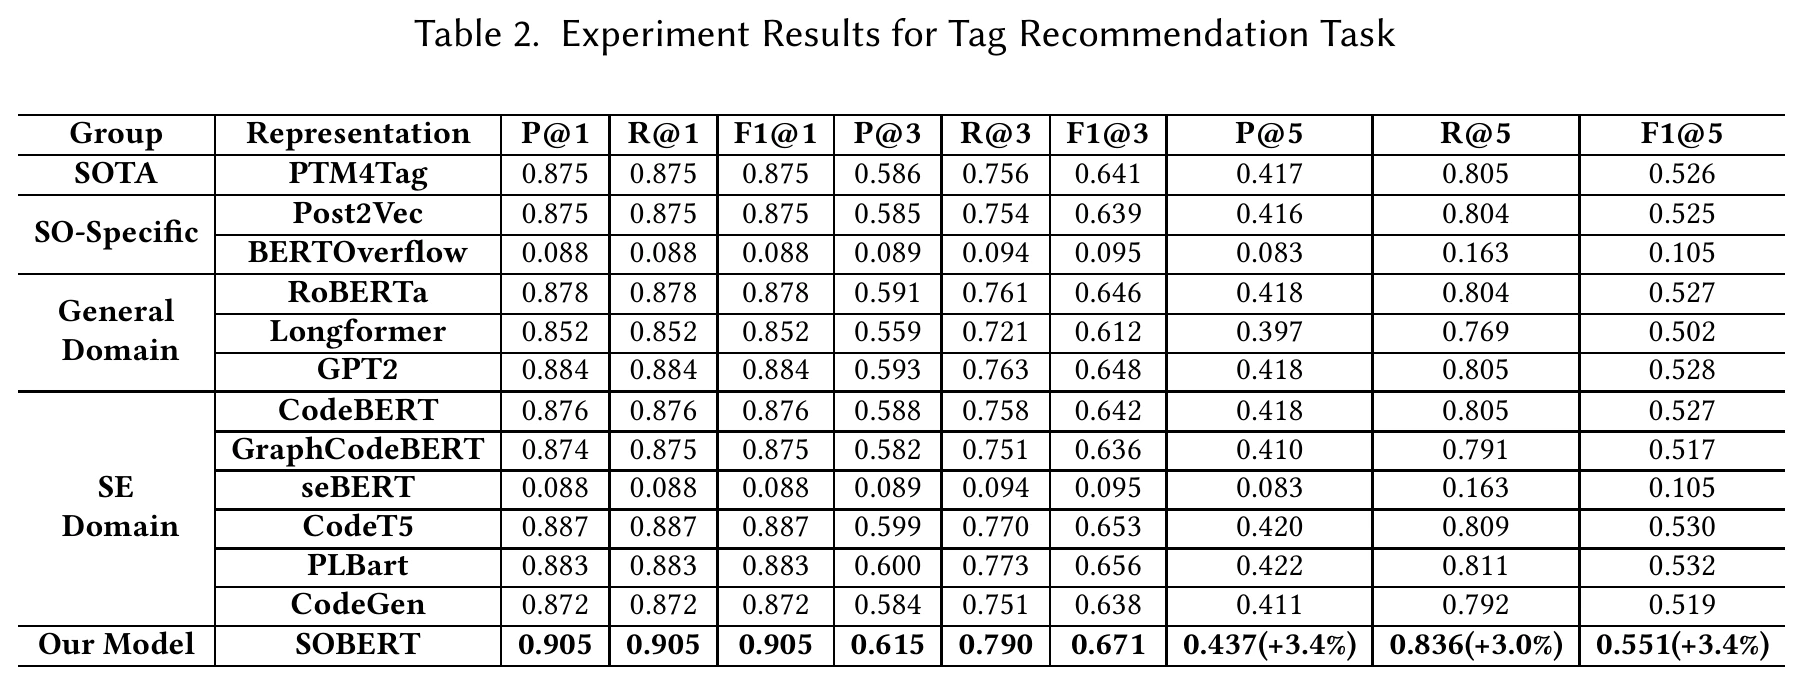
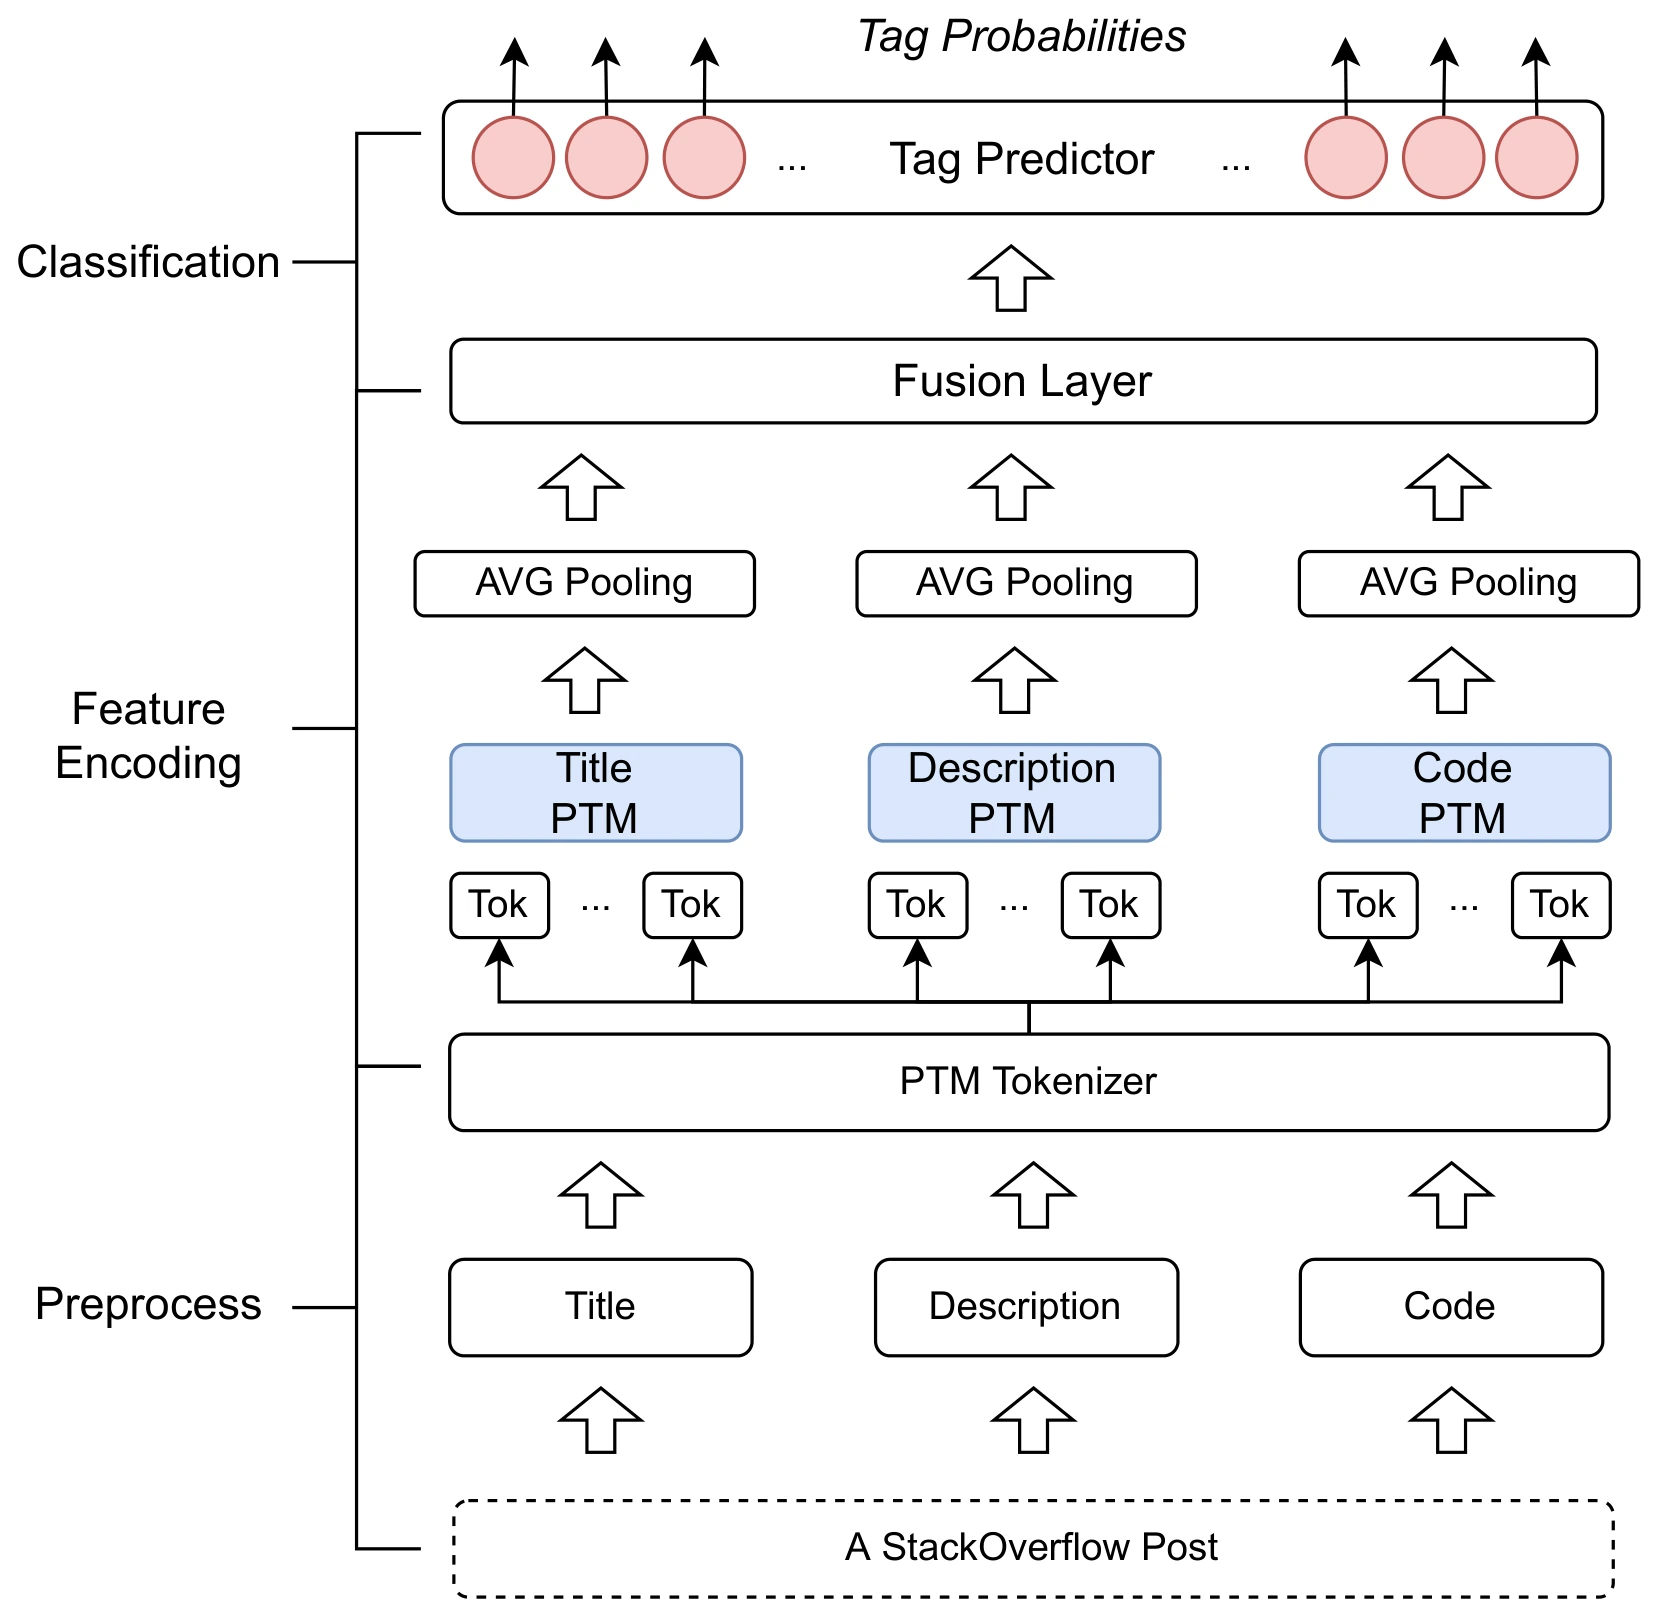
BigCodeBench 2025 SE benchmark assessment 2025 Reference-free BRE evaluation 2026 LessLeak-Bench 2025Pre-trained models for Stack Overflow posts — tag recommendation and a systematic study of post representations.
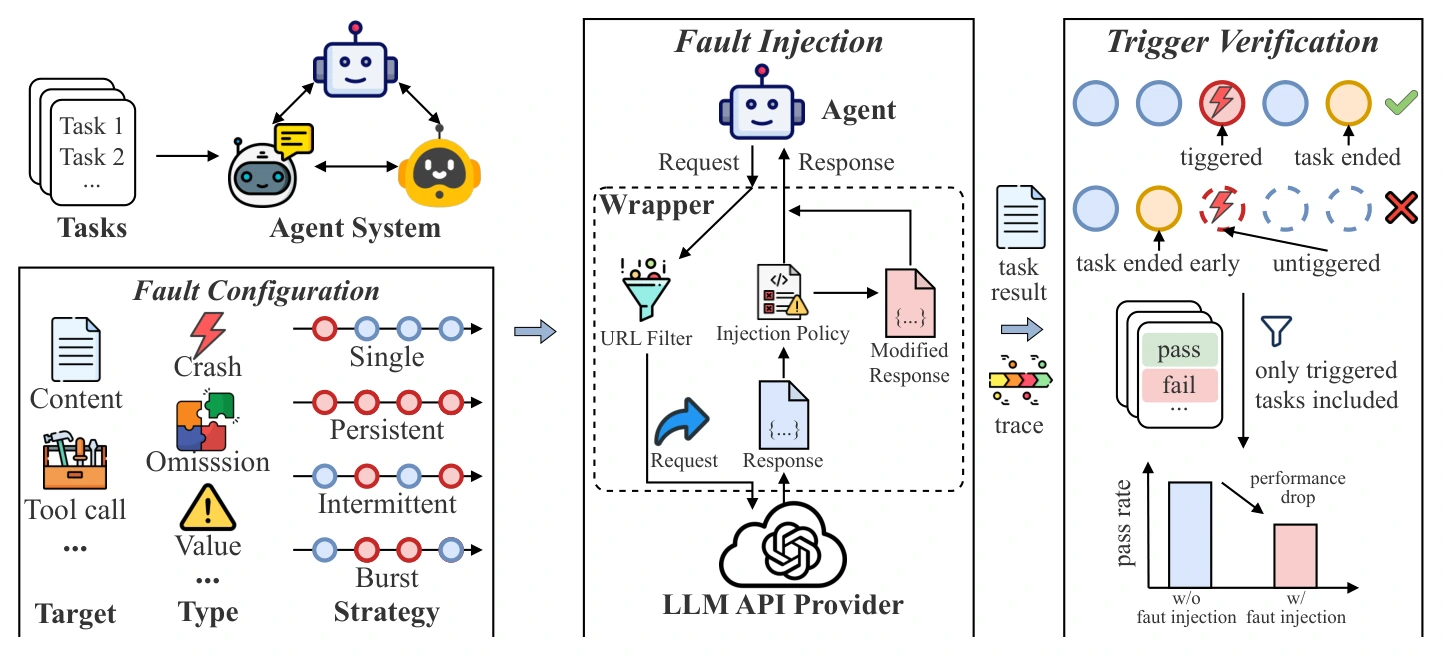
PTM4Tag 2022 PTM4Tag+ 2025 SO post representations 2024AgentChaos: Chaos Engineering for Agent Systems was accepted at ASE 2026.
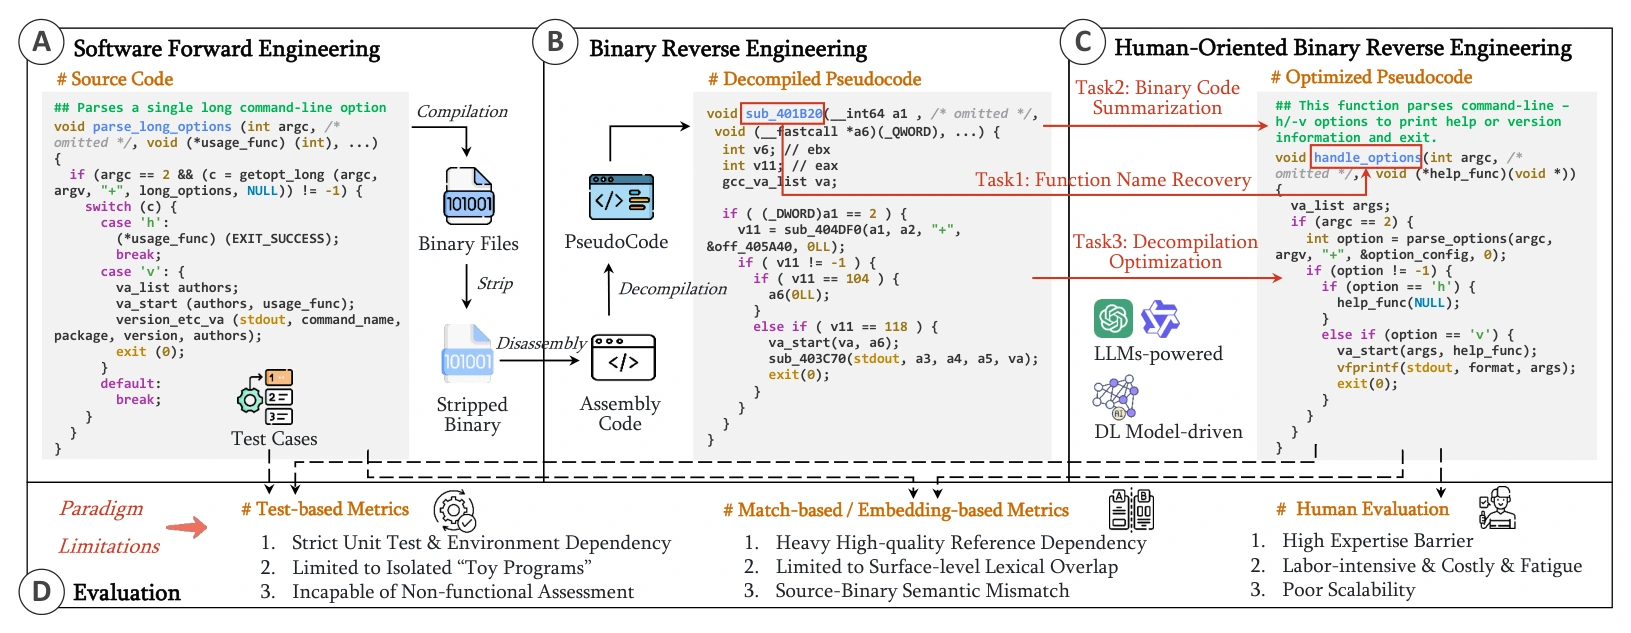
Beyond Text Matching, our work on reference-free evaluation for binary reverse engineering, was accepted at ASE 2026.
Learning from the Test, our work on self-referential differential testing for deep RL agents, was accepted at ISSTA 2026.
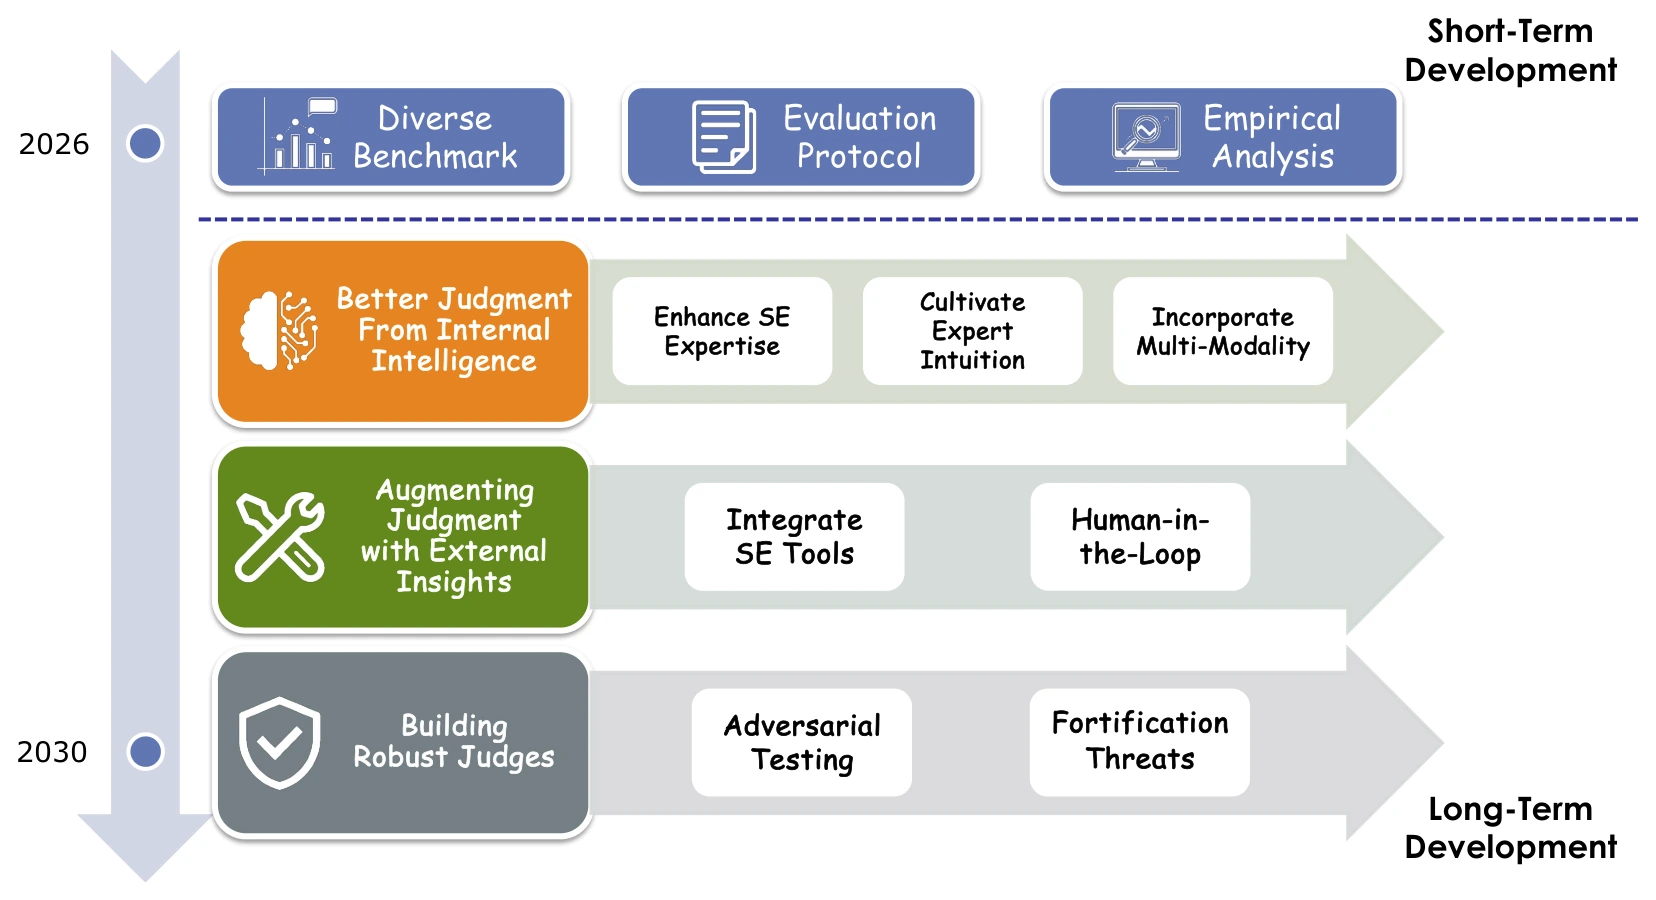
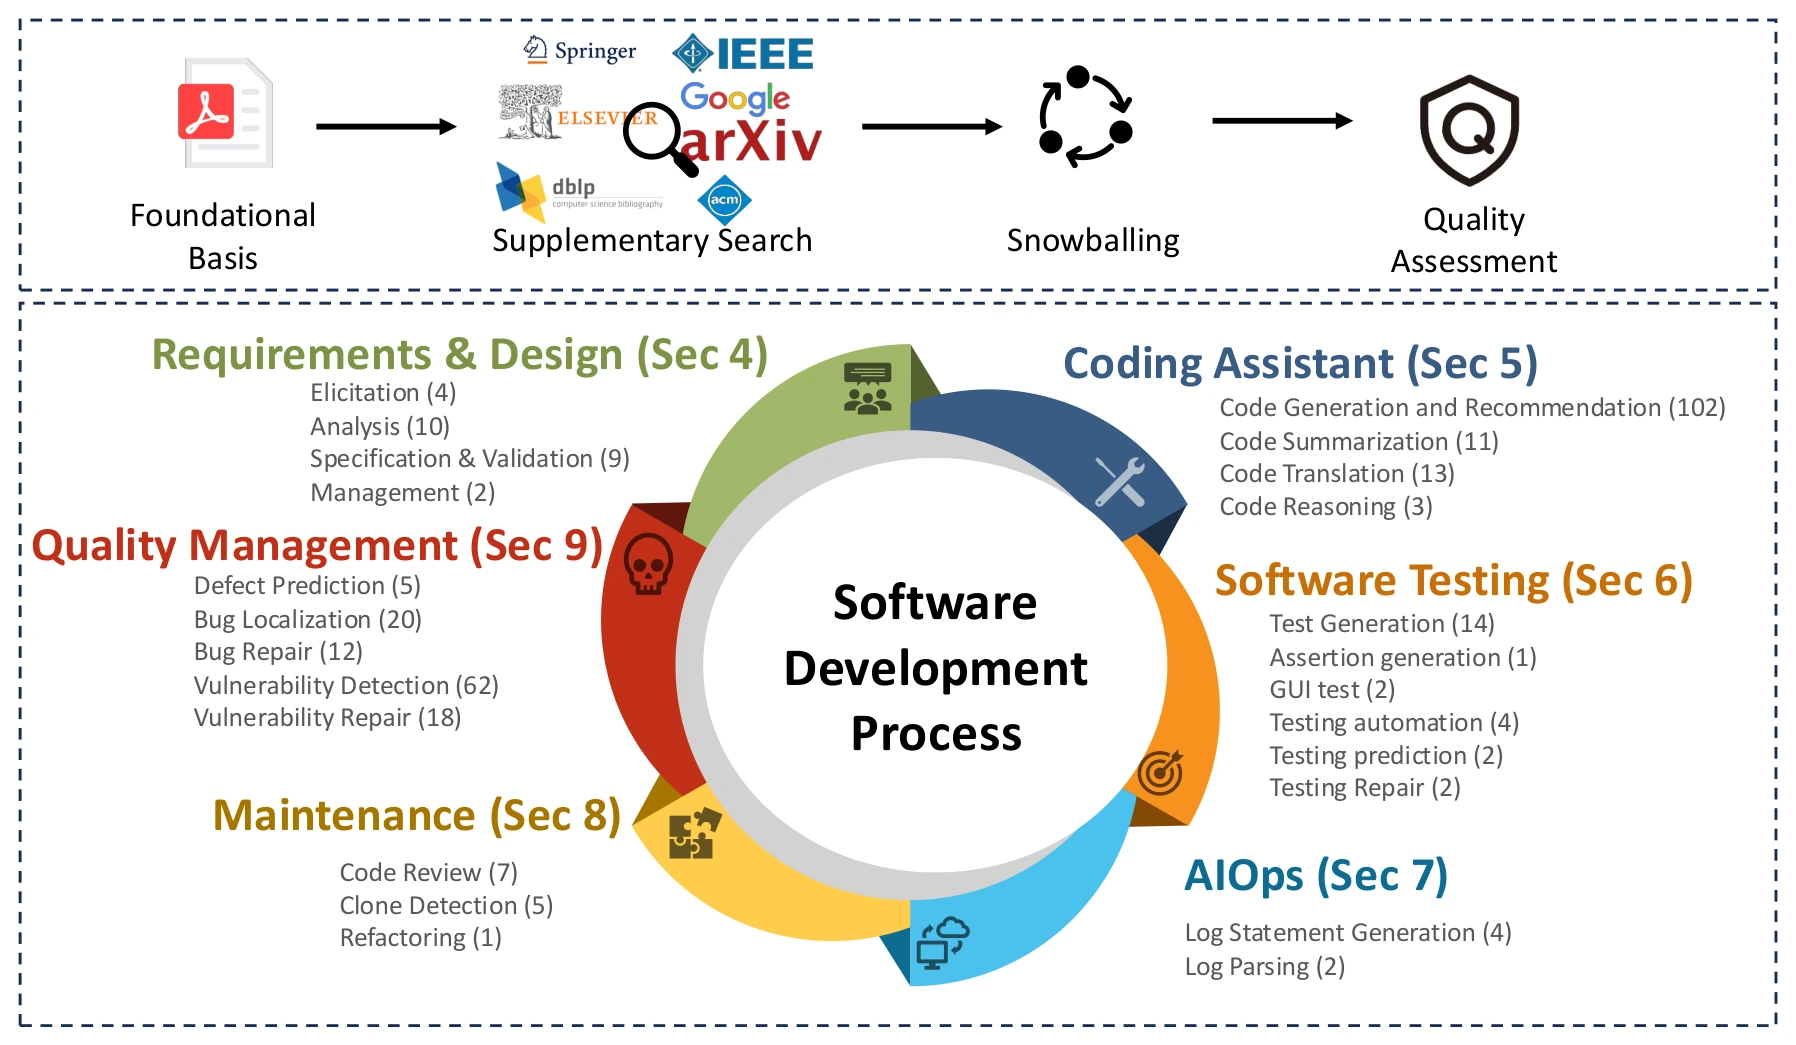
LLM-as-a-Judge for Software Engineering, our literature review and research roadmap, is published in TOSEM.
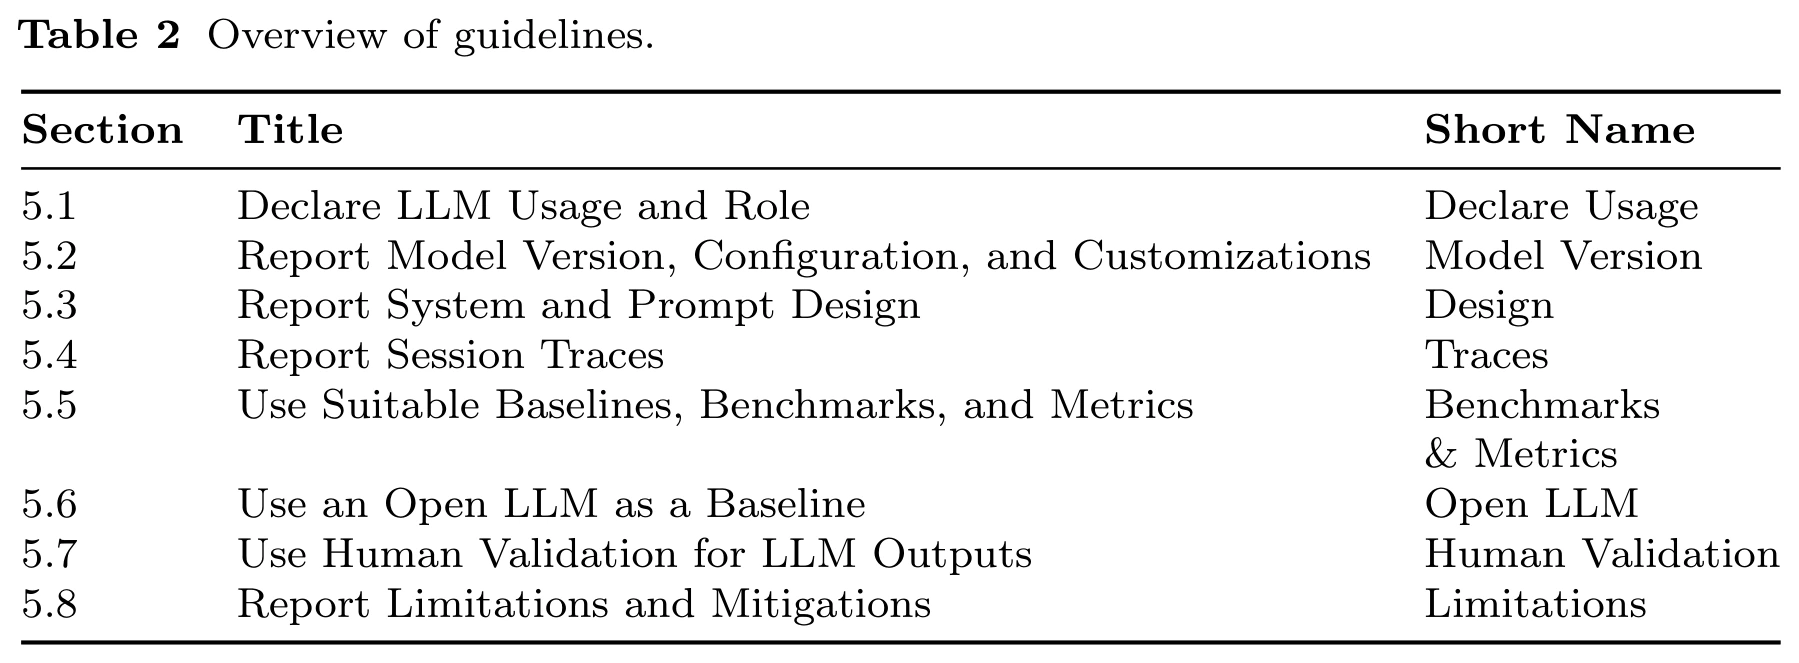
Our community guidelines for empirical SE studies involving LLMs were accepted by EMSE.
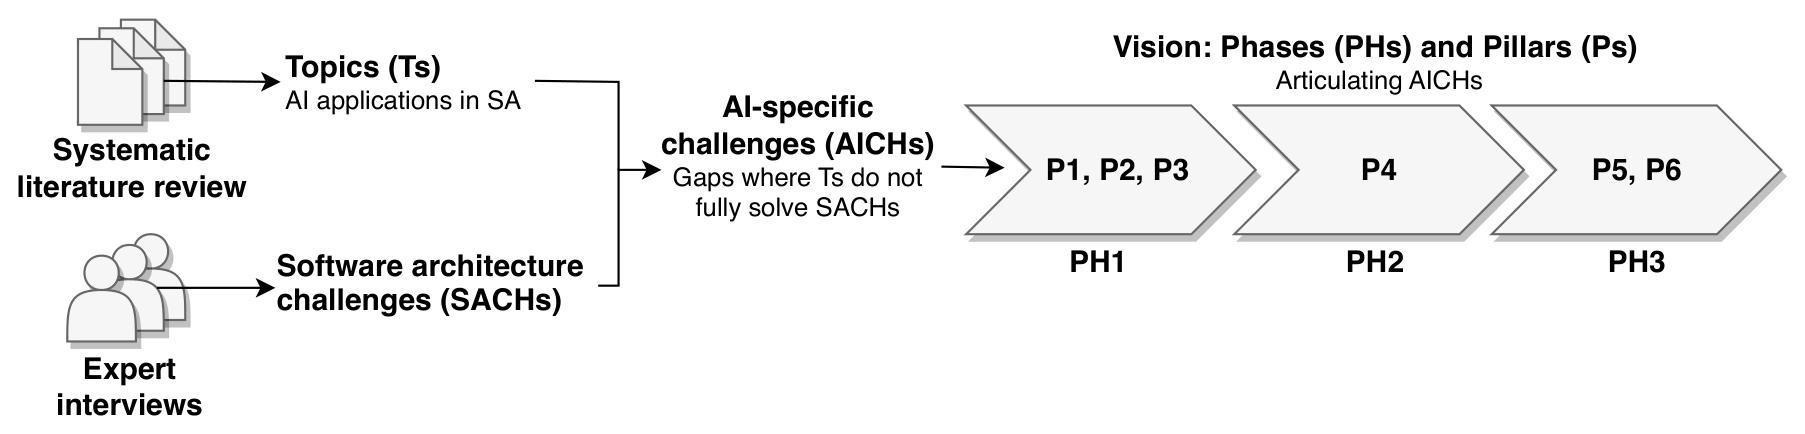
Our systematic review of AI support for software architecture practice is published in TOSEM.
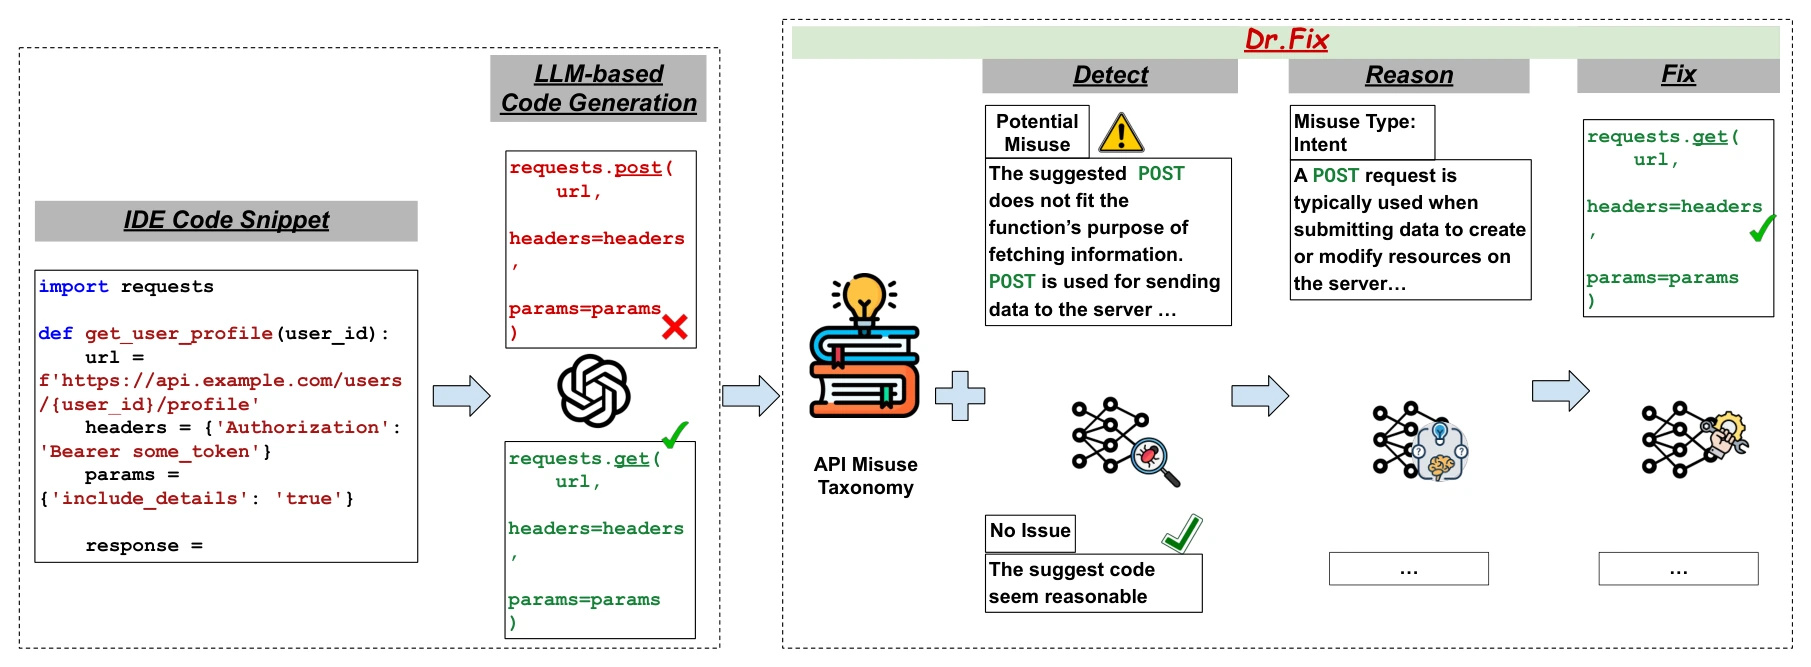
Identifying and Mitigating API Misuse in Large Language Models is published in TSE.
Our work on efficient and permissive runtime shields for neural policies is published in TOSEM.
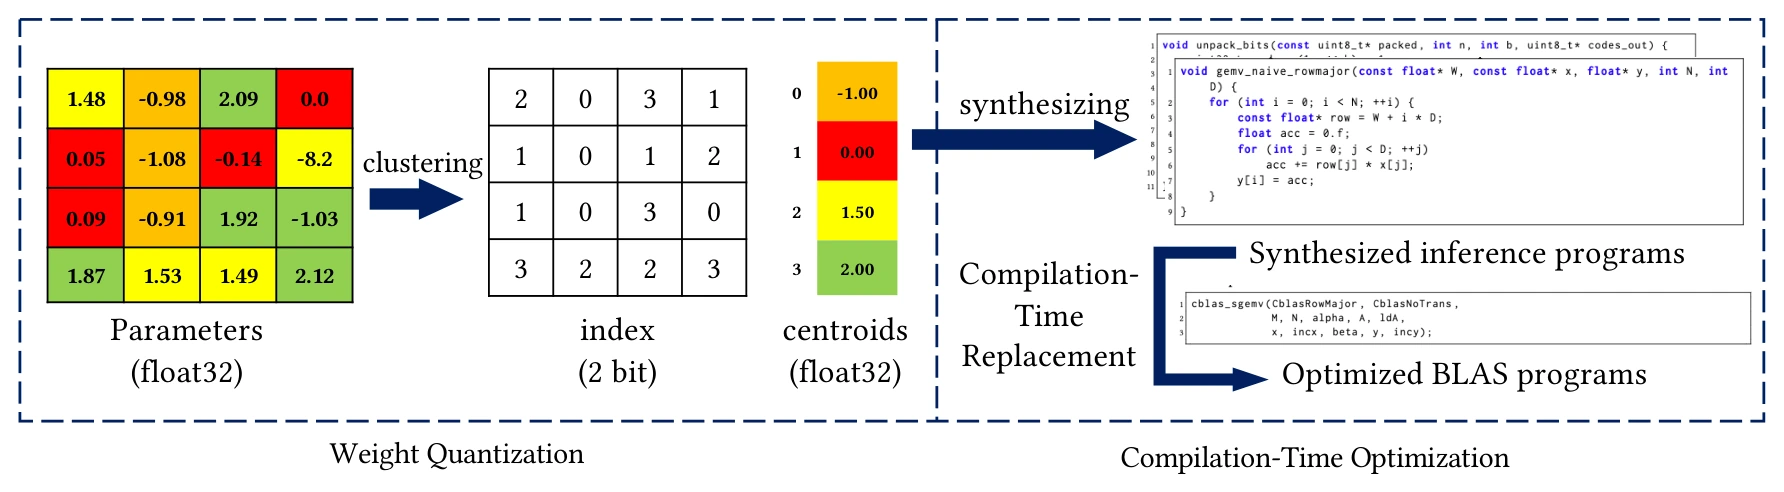
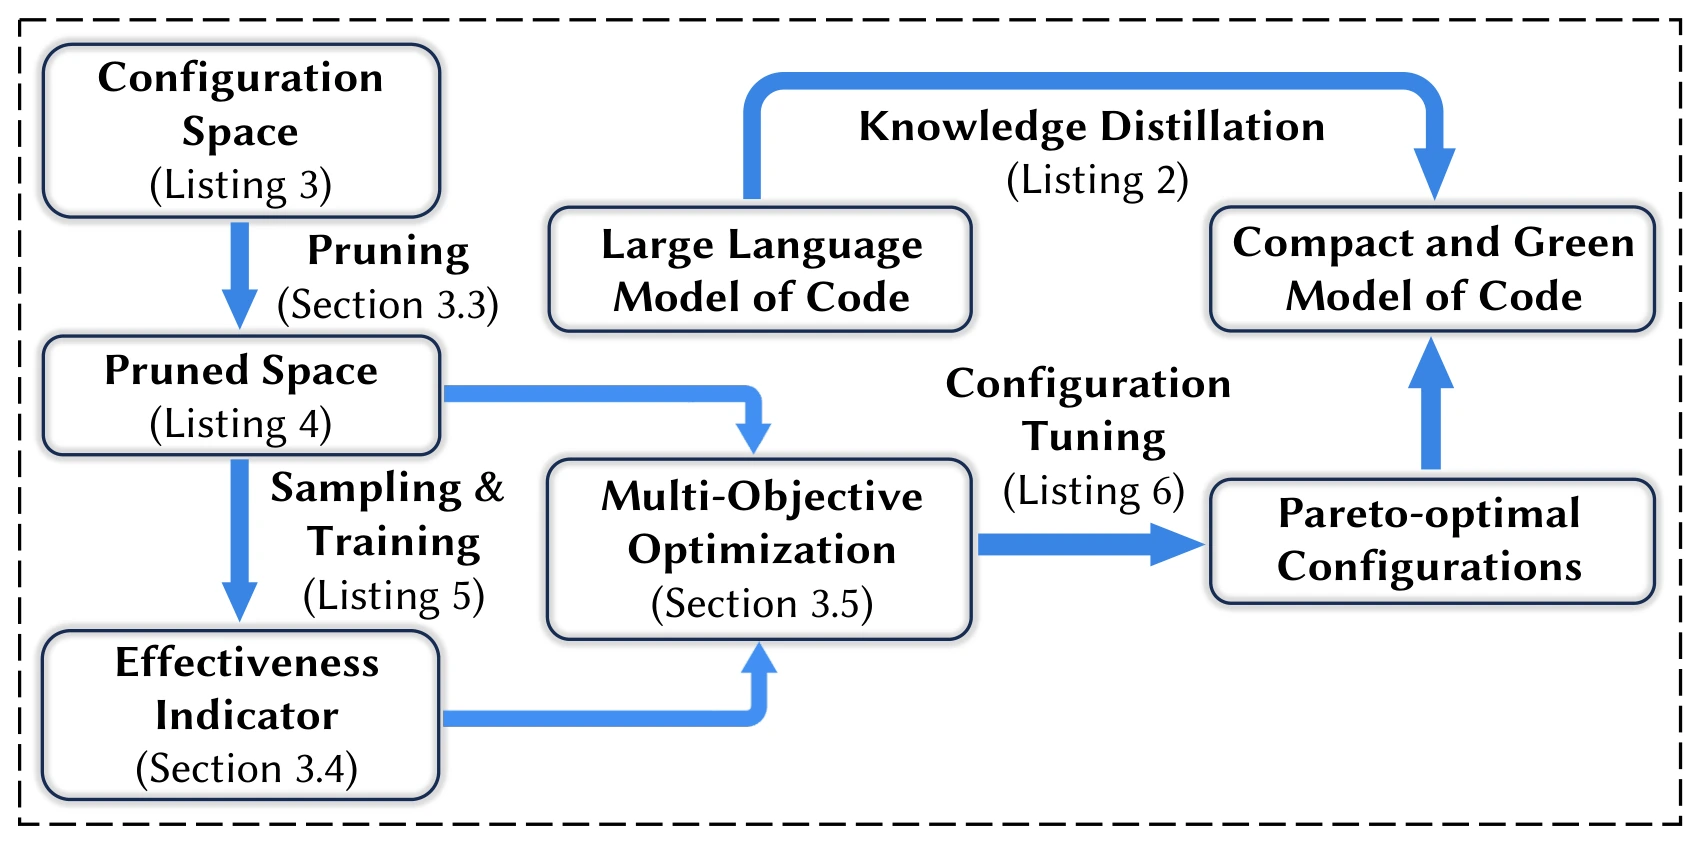
Compiling Code LLMs into Lightweight Executables was accepted at FSE 2026.
Our survey Assessing and Advancing Benchmarks for Evaluating LLMs in SE Tasks is published in TOSEM.
Invited talk at Korea University, Seoul: From Code to Courtroom: LLMs as the New Software Judges.
Invited talk at Osaka University: When LLMs Judge Software: Toward Trustworthy Automated Evaluation.
LLM-Based Multi-Agent Systems for Software Engineering is published in TOSEM, as part of its 2030 roadmap special issue.
BigCodeBench was accepted at ICLR 2025 as an oral presentation.
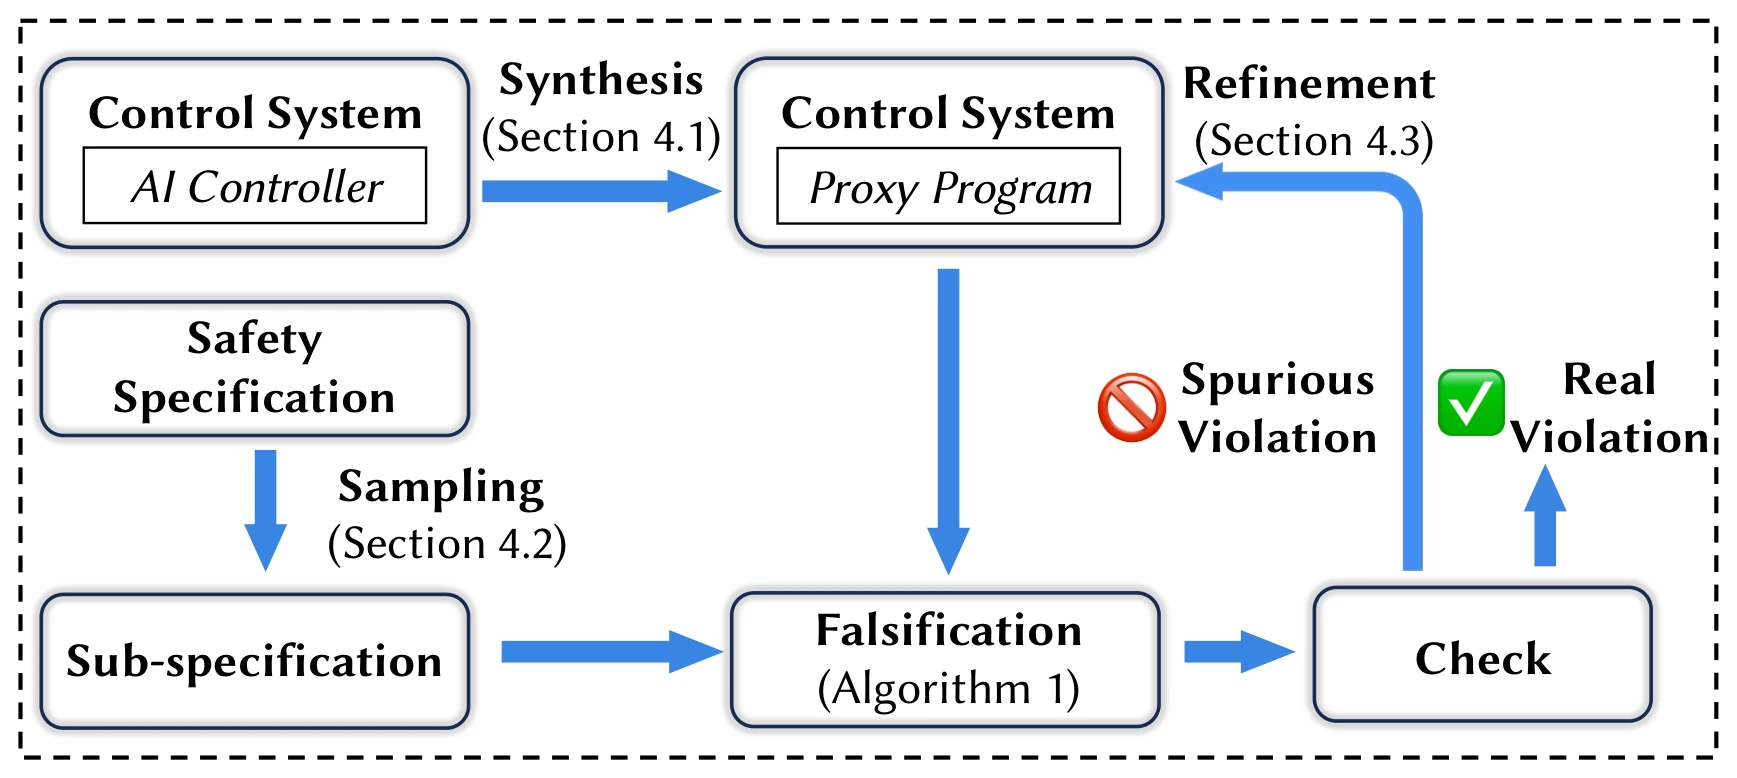
Our work on finding safety violations through synthesized proxy programs was accepted by TOSEM.
Received the SMU PhD Research Excellence Award and was named to the SCIS Dean’s List.
PTM4Tag+, our work on Stack Overflow tag recommendation with pre-trained models, is published online in EMSE (Volume 30, 2025).
Get in touch
For research conversations and collaborations.
School of Computing and Information Systems
Singapore Management University · Singapore
No papers found. Try another title, author, venue or year.